Associated Datadog Illuminated episode: How to Evaluate AI Code against Your Company's Standards
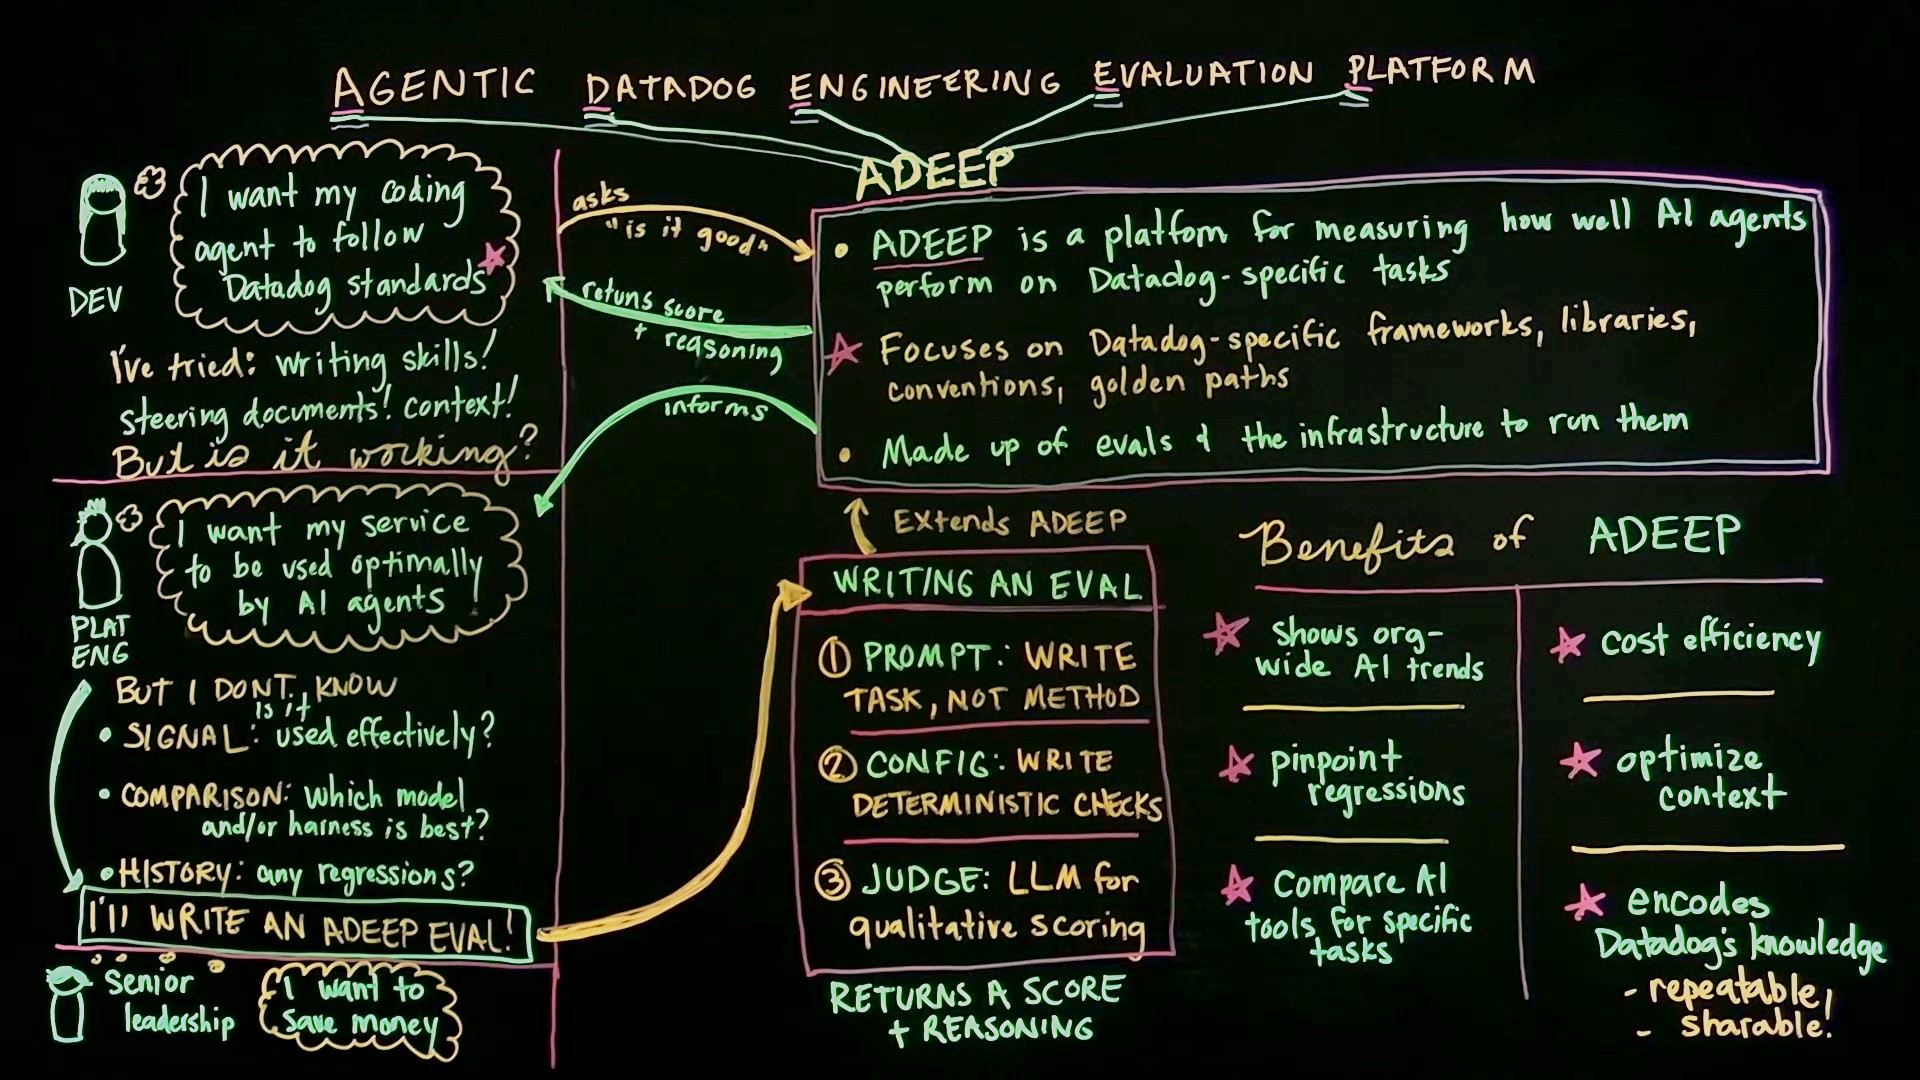
- ADEEP is a platform for measuring how well AI agents perform on Datadog-specific tasks
- ⭐ Focuses on Datadog-specific frameworks, libraries, conventions, golden paths
- Made up of evals & the infrastructure to run them
💭 "I want my coding agent to follow Datadog standards"
I've tried:
- Writing Skills
- Steering Documents
- Context
But is it working?
Ask ADEEP: is it good? ADEEP returns: score and reasoning
💭 "I want my service to be used optimally by AI agents"
But I don't know:
- Signal: Is it used effectively?
- Comparison: Which model and/or harness is best?
- History: Any regressions for each of those questions?
I'll WRITE AN ADEEP EVAL!
Writing an eval extends ADEEP, and ADEEP eval results inform the Platform Engineer.
💭 "I want to save money"
- PROMPT: WRITE TASK, NOT METHOD
- CONFIG: WRITE DETERMINISTIC CHECKS
- JUDGE: LLM for qualitative scoring
RETURNS A SCORE + REASONING
- ⭐ Shows org-wide AI trends
- ⭐ Pinpoint regressions
- ⭐ Compare AI tools for specific tasks
- ⭐ Cost efficiency
- ⭐ Optimize context
- ⭐ Encodes Datadog's knowledge
- Repeatable
- Sharable